In Simple Words
Imagine selecting the best players for a sports team by running hundreds of mini-scrimmages with randomly picked sub-groups of athletes; players who consistently perform well across almost every random match-up are the true star performers.
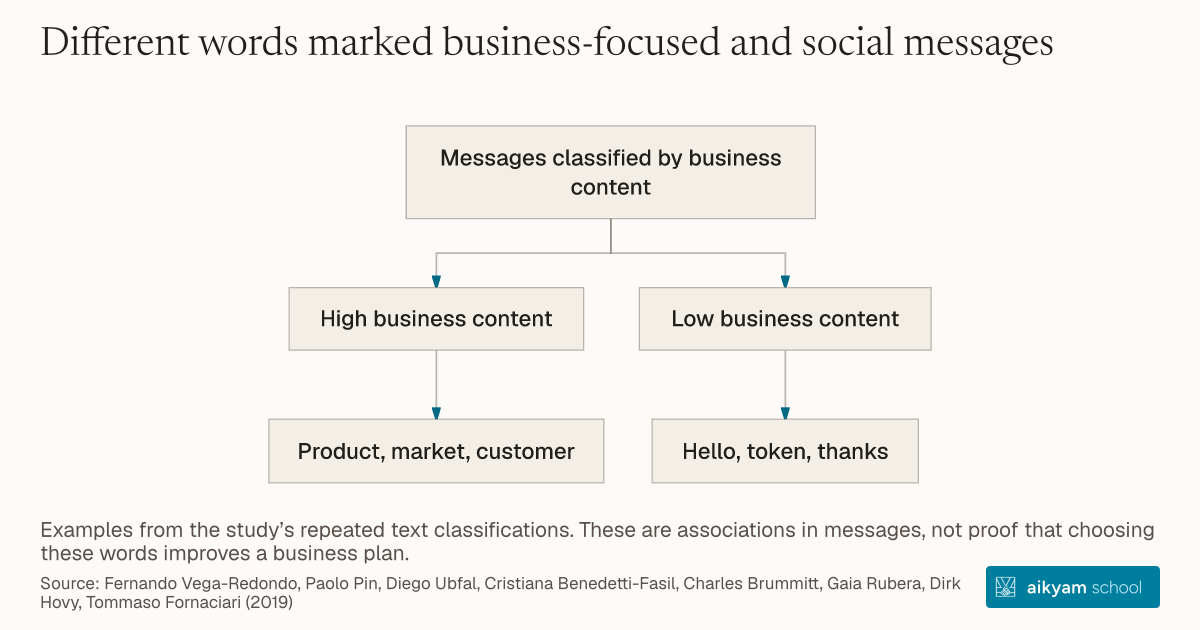
Messages classified by business content
- High business content
- Product, market, customer
- Low business content
- Hello, token, thanks
Examples from the study’s repeated text classifications. These are associations in messages, not proof that choosing these words improves a business plan.
See source →Research question
High-dimensional text corpora contain thousands of sparse words, making standard regression models prone to overfitting when isolating key linguistic features.
Participants
N = 140,000+ messages written by 4,958 entrepreneurs across 49 African countries.
Study Design
Bootstrapped fitting of 200 to 1,000 $l_1$-penalized LASSO logistic regressions on random sub-samples drawn with replacement, selecting words with non-zero coefficients in >50% of iterations.
Results
High business content is reliably flagged by terms like product, project, business, market, idea, need, customer, service, plan, and cost, whereas low business content is flagged by hello, hi, token, leaderboard, status, and thanks.
Takeaway
Apply stability selection with $l_1$ LASSO penalization across repeated random bootstrap sub-samples to identify stable text regressors in high-dimensional communication data.