In Simple Words
Think of a local neighborhood like a small village square where neighbors constantly observe each other's work ethic, customer foot traffic, and business operations over many years. While outside bank inspectors only see superficial paperwork, community peers hold informal, deep knowledge about who possesses genuine business talent. By asking peer groups of five neighboring business owners to privately rank each other's growth prospects, program organizers aggregate distributed local intelligence to reveal hidden high-ability talent.
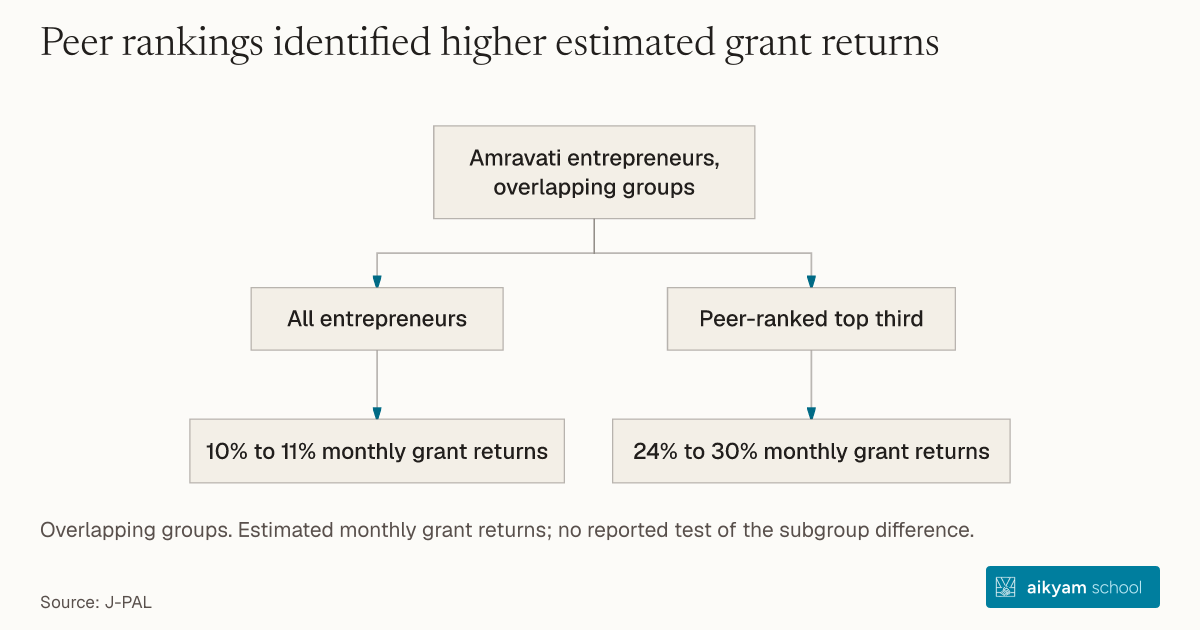
Amravati entrepreneurs, overlapping groups
- All entrepreneurs
- 10% to 11% monthly grant returns
- Peer-ranked top third
- 24% to 30% monthly grant returns
The peer-ranked top third is part of the full sample. Higher estimated grant returns do not establish a causal effect of selecting entrepreneurs by peer rank.
See source →Research question
Microfinance institutions struggle to identify high-potential microentrepreneurs due to a lack of verifiable information and concrete financial data. Traditional microcredit yields limited average impacts because lenders cannot easily target capital grants or credit to entrepreneurs with the highest potential return on investment.
Participants
1,345 households across nine peri-urban neighborhoods organized into 274 peer groups of five in Amravati, Maharashtra, India.
Study Design
Randomized controlled trial (RCT) assigning participants to rank peers, with a random one-third selected to receive a US$100 cash grant, evaluated across baseline and four follow-up surveys.
Results
Entrepreneurs ranked in the top third by peers achieved monthly returns of 24% to 30% on cash grants (around 3 times the average return of 10% to 11%), and combining observable traits with peer information yielded 38% monthly returns.
Takeaway
Implement peer-group ranking surveys among geographically clustered microentrepreneurs to identify candidates for high-yield capital grants before dispersing credit.
Source and citation
See source →Read alongside the research
Plain-English glossary
Original explanations, informed by the references below. Examples are illustrations, not data from the studies above. The research text stays unchanged.
- Follow-up
Collecting more information about participants later in a study to see what has happened to them. The term can also mean the length of time researchers keep track of them.
ExampleResearchers interview the same workers three months after a programme ends. That later interview is a follow-up.
GET-IT glossary · Follow-up ↗Read more about follow-up →- Baseline
The starting measurements in a study. Researchers use these to compare what participants were like at the start with what happens later.
ExampleBefore a training programme starts, researchers measure workers’ earnings. That first measurement is the baseline.
GET-IT glossary · Baseline characteristics ↗Read more about baseline →- Randomized controlled trial
A study that uses chance, like drawing lots, to decide who receives each option being compared. Researchers compare the groups’ outcomes to estimate the effect of those options.
ExampleA lottery assigns volunteers to a training programme or a comparison group. Researchers then compare their outcomes.
GET-IT glossary · Randomized study ↗Read more about randomized controlled trial →