In Simple Words
Imagine trying to guess if a new coaching style helps specific athletes. Instead of looking at an athlete's own score to decide if the coaching worked for them, you use data from half the team to build a predictive rule, and then test that rule on the other half. Because an athlete's predicted benefit is calculated strictly from everyone else's results, you guarantee that your prediction is unbiased and honest.
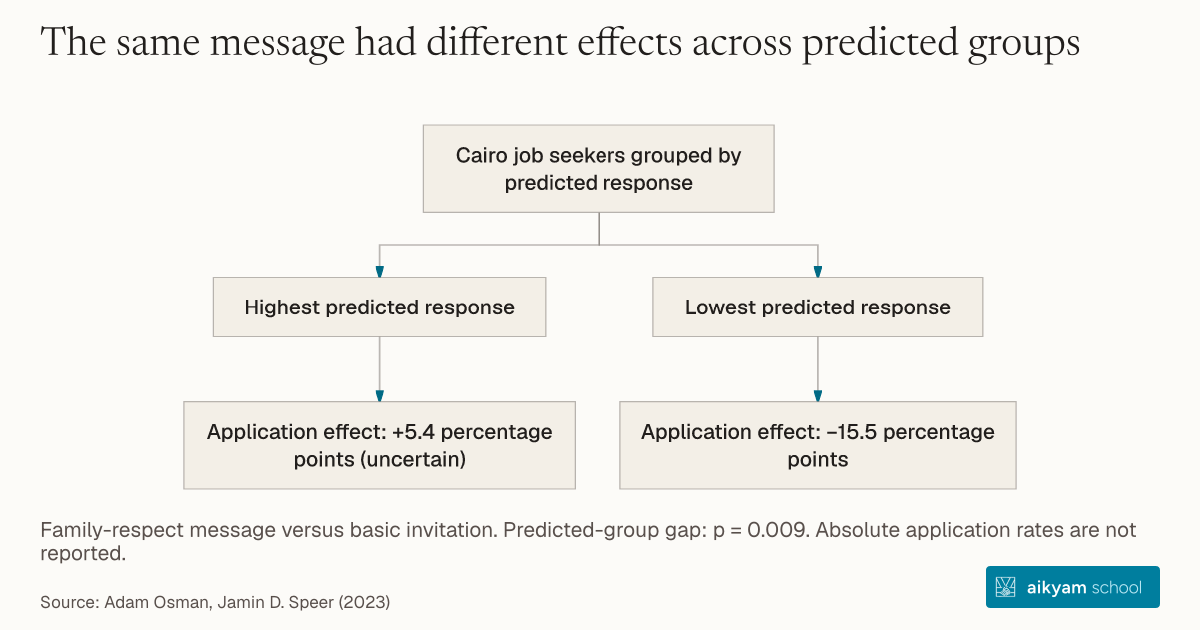
Cairo job seekers grouped by predicted response
- Highest predicted response
- Application effect: +5.4 percentage points (uncertain)
- Lowest predicted response
- Application effect: −15.5 percentage points
In Experiment 1, model-defined groups had different application responses to the social-stigma message: +5.4 percentage points in the highest predicted-response group (uncertain) versus −15.5 points in the lowest. The direct group-difference test gives p = 0.009. Predicted groups are formed with out-of-sample information, as described in the methods appendix.
See source →Research question
Standard subgroup analysis in policy interventions risks data-mining and false positives when searching across multi-dimensional participant attributes. Detecting true treatment effect variation requires agnostic, out-of-sample machine learning predictions that prevent an individual's own outcome from biasing their predicted treatment effect.
Participants
N = 1,460 jobseekers (Experiment 1) and N = 768 jobseekers (Experiment 2) in Cairo, Egypt.
Study Design
Randomized Field Experiment applying Chernozhukov et al. (2022) generic machine learning framework with 100 repeated random split-sample cross-validations using Lasso, Elastic Net, Boosted Trees, and Random Forest algorithms to estimate Sorted Group Average Treatment Effects (GATES).
Results
Identified statistically significant treatment effect divergence between the top and bottom predicted individual treatment effect (ITE) quintiles for social stigma (p = 0.009 in Exp 1, p = 0.022 in Exp 2) and professional stigma (p = 0.015 in Exp 1), uncovering hidden heterogeneity where average treatment effects were near zero.
Takeaway
Apply split-sample machine learning algorithms to baseline data in randomized trials to evaluate subgroup variation instead of performing ad-hoc post-hoc subgroup tests.
Source and citation
See source →Read alongside the research
Plain-English glossary
Original explanations, informed by the references below. Examples are illustrations, not data from the studies above. The research text stays unchanged.
- Baseline
The starting measurements in a study. Researchers use these to compare what participants were like at the start with what happens later.
ExampleBefore a training programme starts, researchers measure workers’ earnings. That first measurement is the baseline.
GET-IT glossary · Baseline characteristics ↗Read more about baseline →- Statistically significant
A label used when a result passes a chosen statistical threshold, often p < 0.05. It does not show how large or useful an effect is. A result that is not statistically significant does not prove there is no effect.
ExampleA study reports p = 0.03 against a 0.05 threshold. It passes that test, but the effect could still be too small to matter.
American Statistical Association · Statement on p-values ↗Read more about statistically significant →